What Is a Apache Cassandra Index?
An index is a data structure that helps the database find candidate records without scanning every row. It can accelerate matching queries but requires storage and maintenance during writes.
How Apache Cassandra Index Algorithms Work
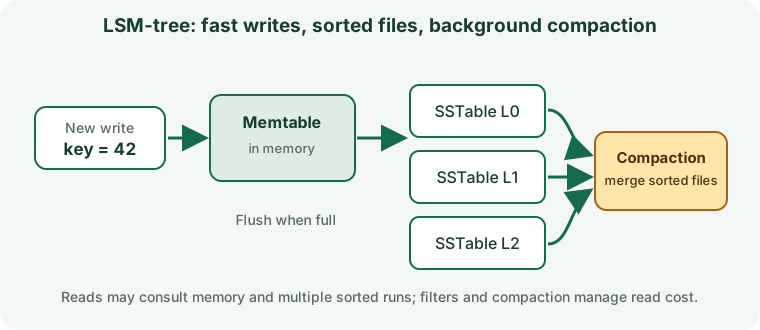
Cassandra is a distributed, partitioned LSM-tree database. Primary-key design routes queries to partitions; supported secondary indexes such as SAI add search structures. It does not use a relational B-tree index model.
Apache Cassandra Index Types and Individual Guides
Each link opens its own guide with an algorithm image, create/query example, use cases, limitations, and tuning steps.
- ALLOW FILTERING and Index Alternatives
- Clustering Columns and Order
- Indexes on Collections
- Custom Index Implementations
- Materialized Views as a Query Alternative
- Partition Keys
- Primary-Key Indexing and Query Routing
- Storage-Attached Indexing (SAI)
- SASI Indexes (Legacy)
- Traditional Secondary Indexes (2i)
- Storage-Attached Vector Indexes
Which Apache Cassandra Index Should I Use?
Design the primary key around known query patterns first. Use Cassandra 5 Storage-Attached Indexing for supported non-primary-key searches, and treat older secondary-index approaches and materialized views as version- and workload-dependent.
Start with the query workload, required consistency, ordering, data distribution, and write rate. Do not select a structure from its name alone.
Match Indexes to Filters, Sorts, and Joins
Write down the actual predicates, sort keys, joins, and returned columns. The order of keys and supported operators determine whether the engine can use an index.
How to Read Apache Cassandra Query Plans
Use the engine's explain or execution-plan tooling to compare estimated and actual rows, keys examined, pages read, sorting, filtering, and lookup operations.
Index Storage and Write Performance
Indexes use disk and cache and add work to inserts, updates, and deletes. Specialized indexes may emit multiple entries per row or maintain separate structures.
Index Statistics and Maintenance
Monitor size, usage, build state, selectivity, fragmentation or compaction where relevant, and write latency. Make maintenance changes using the engine's version-specific procedures.
Common Apache Cassandra Indexing Mistakes
- Adding indexes without checking real query plans.
- Ignoring key order, operator compatibility, or data distribution.
- Assuming an index removes all filtering or row-fetch work.
- Forgetting write amplification, backups, and deployment impact.
Apache Cassandra Index Version and Feature Notes
Available index types and behavior vary by engine release, storage engine, extension, edition, data type, and operator. Verify each feature against the database actually deployed.
Official reference: Apache Cassandra documentation: Indexing concepts.
Apache Cassandra Indexing Questions
Does adding an index guarantee a faster query?
No. The optimizer may choose a table or partition scan when many rows match or index lookups would cost more.
Should every searchable column have an index?
No. Index only measured workloads and account for maintenance, storage, and data distribution.